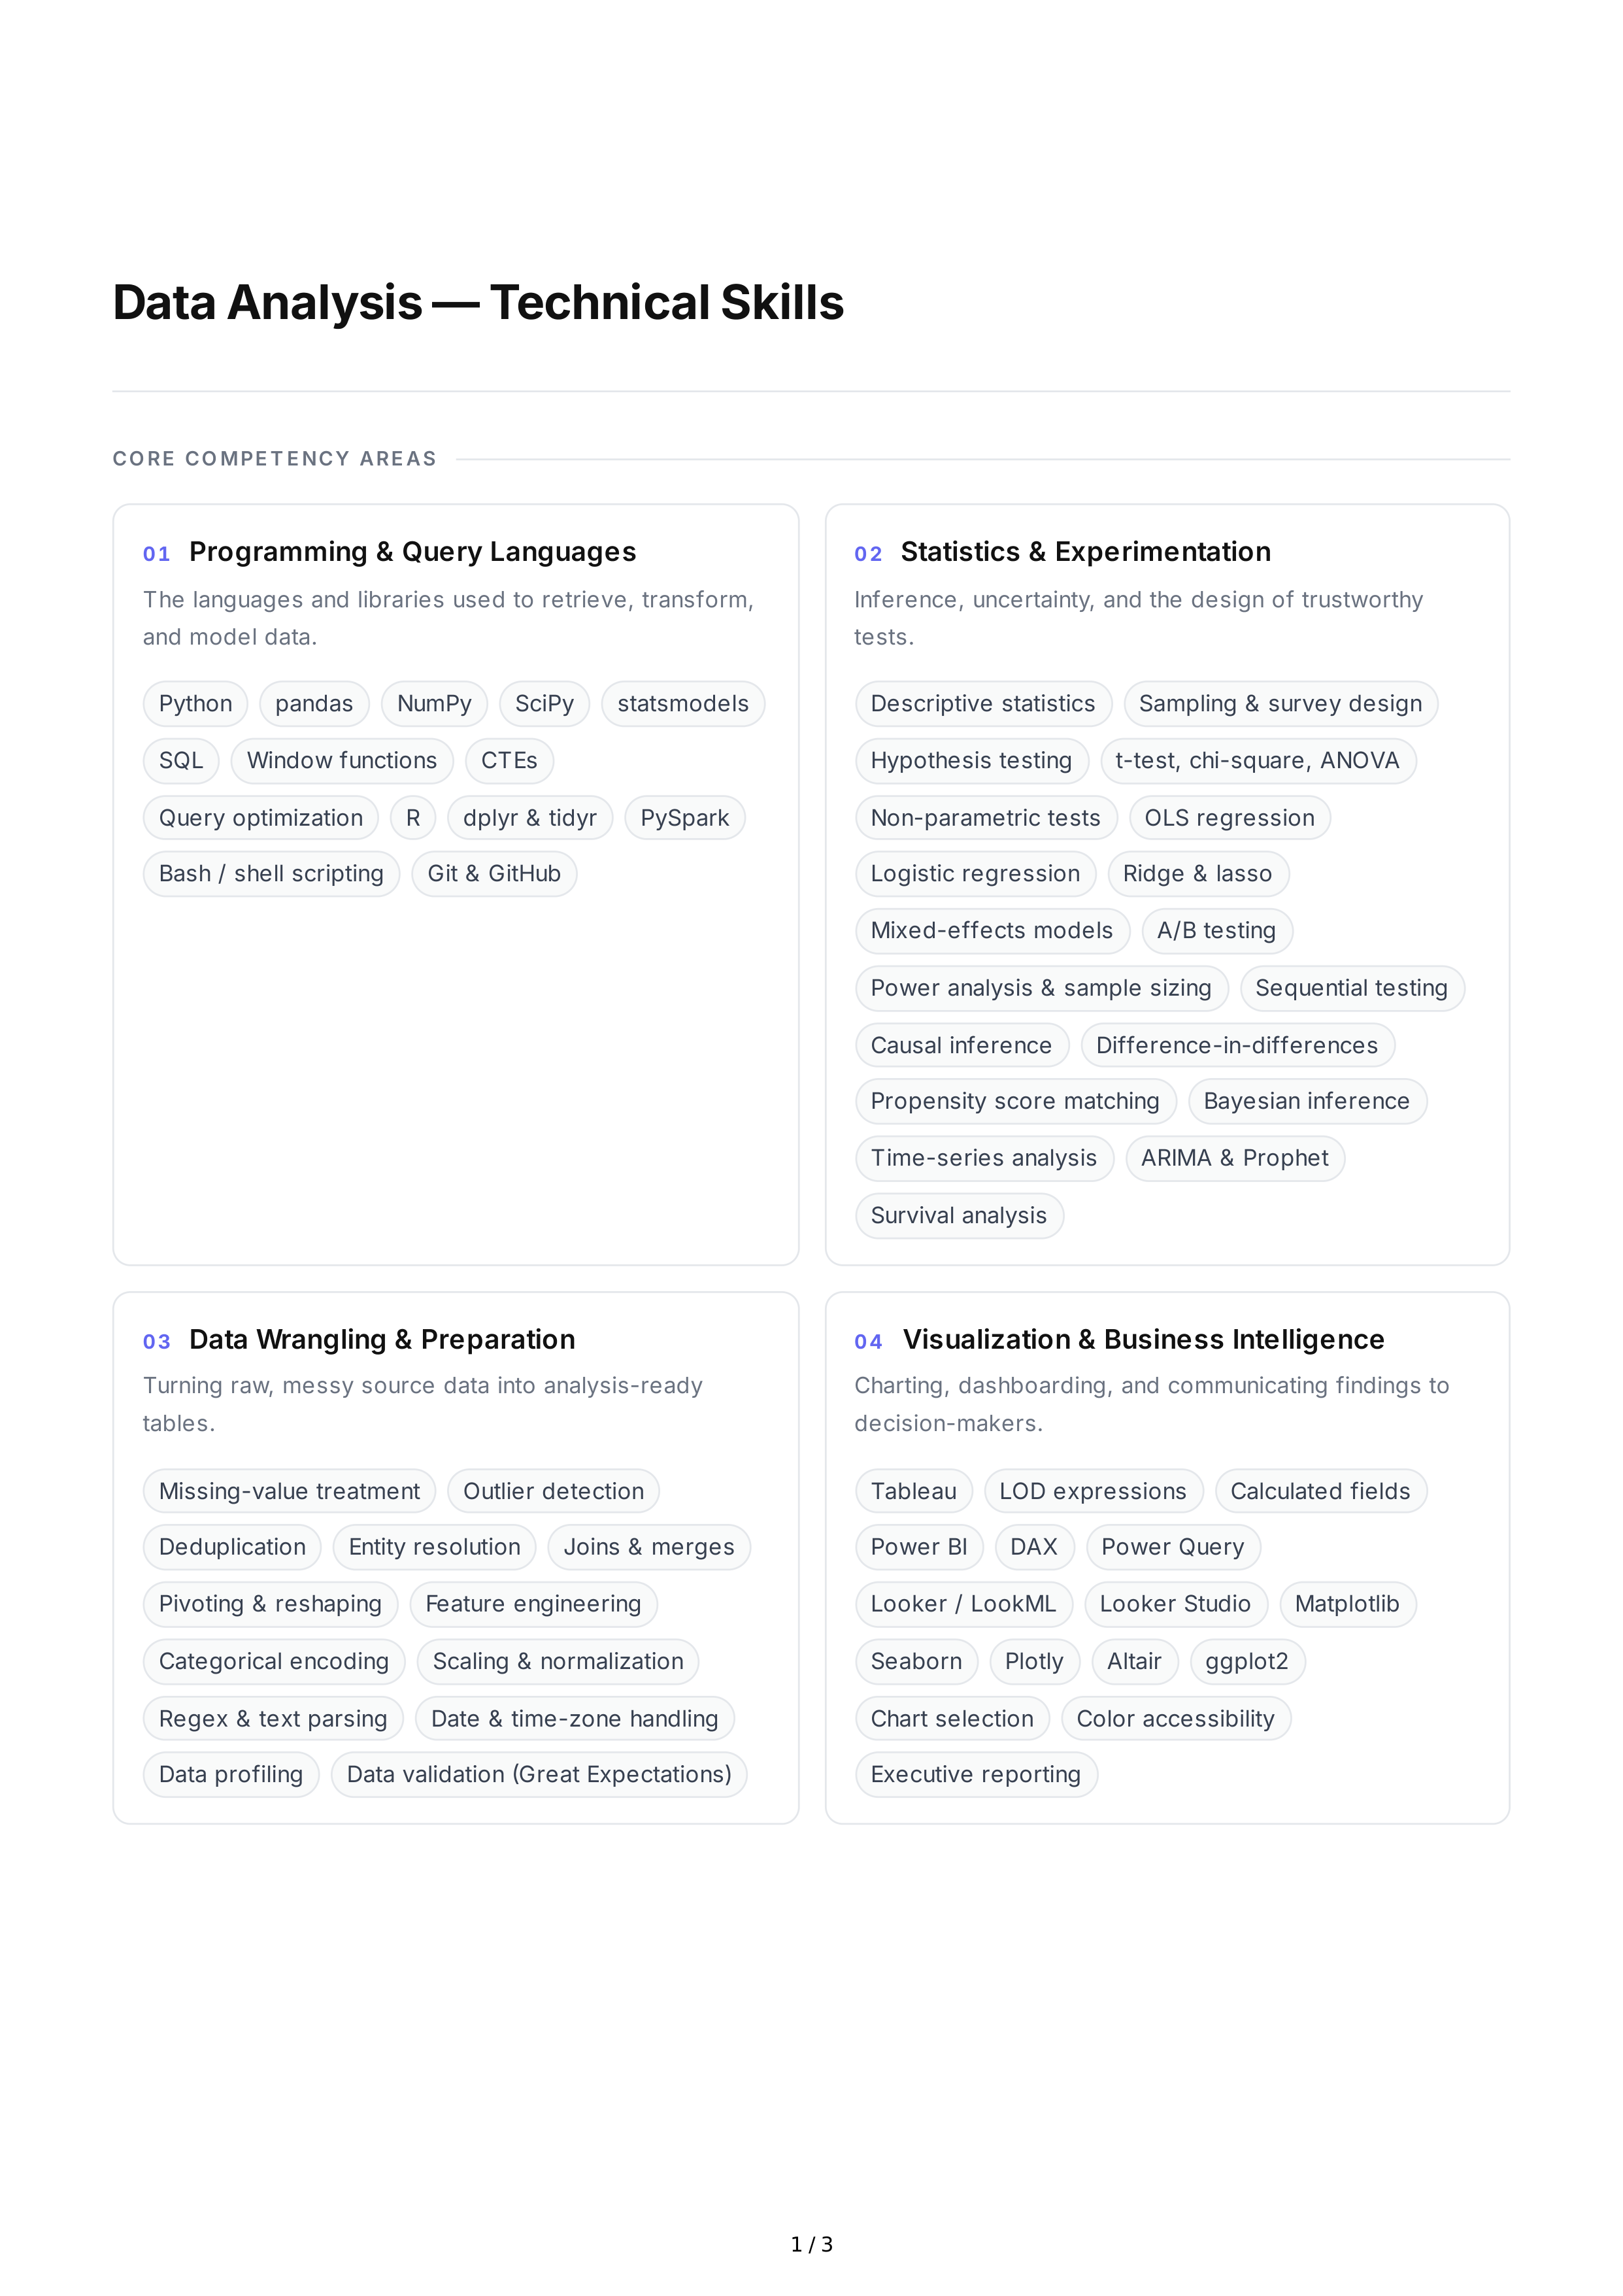
Data
Analysis
—
Technical
Skills
CO RE
CO MPE T E NCY
ARE AS
01
Programming
&
Query
Languages
The
languages
and
libraries
used
to
retrieve
,
transform
,
and
model
data
.
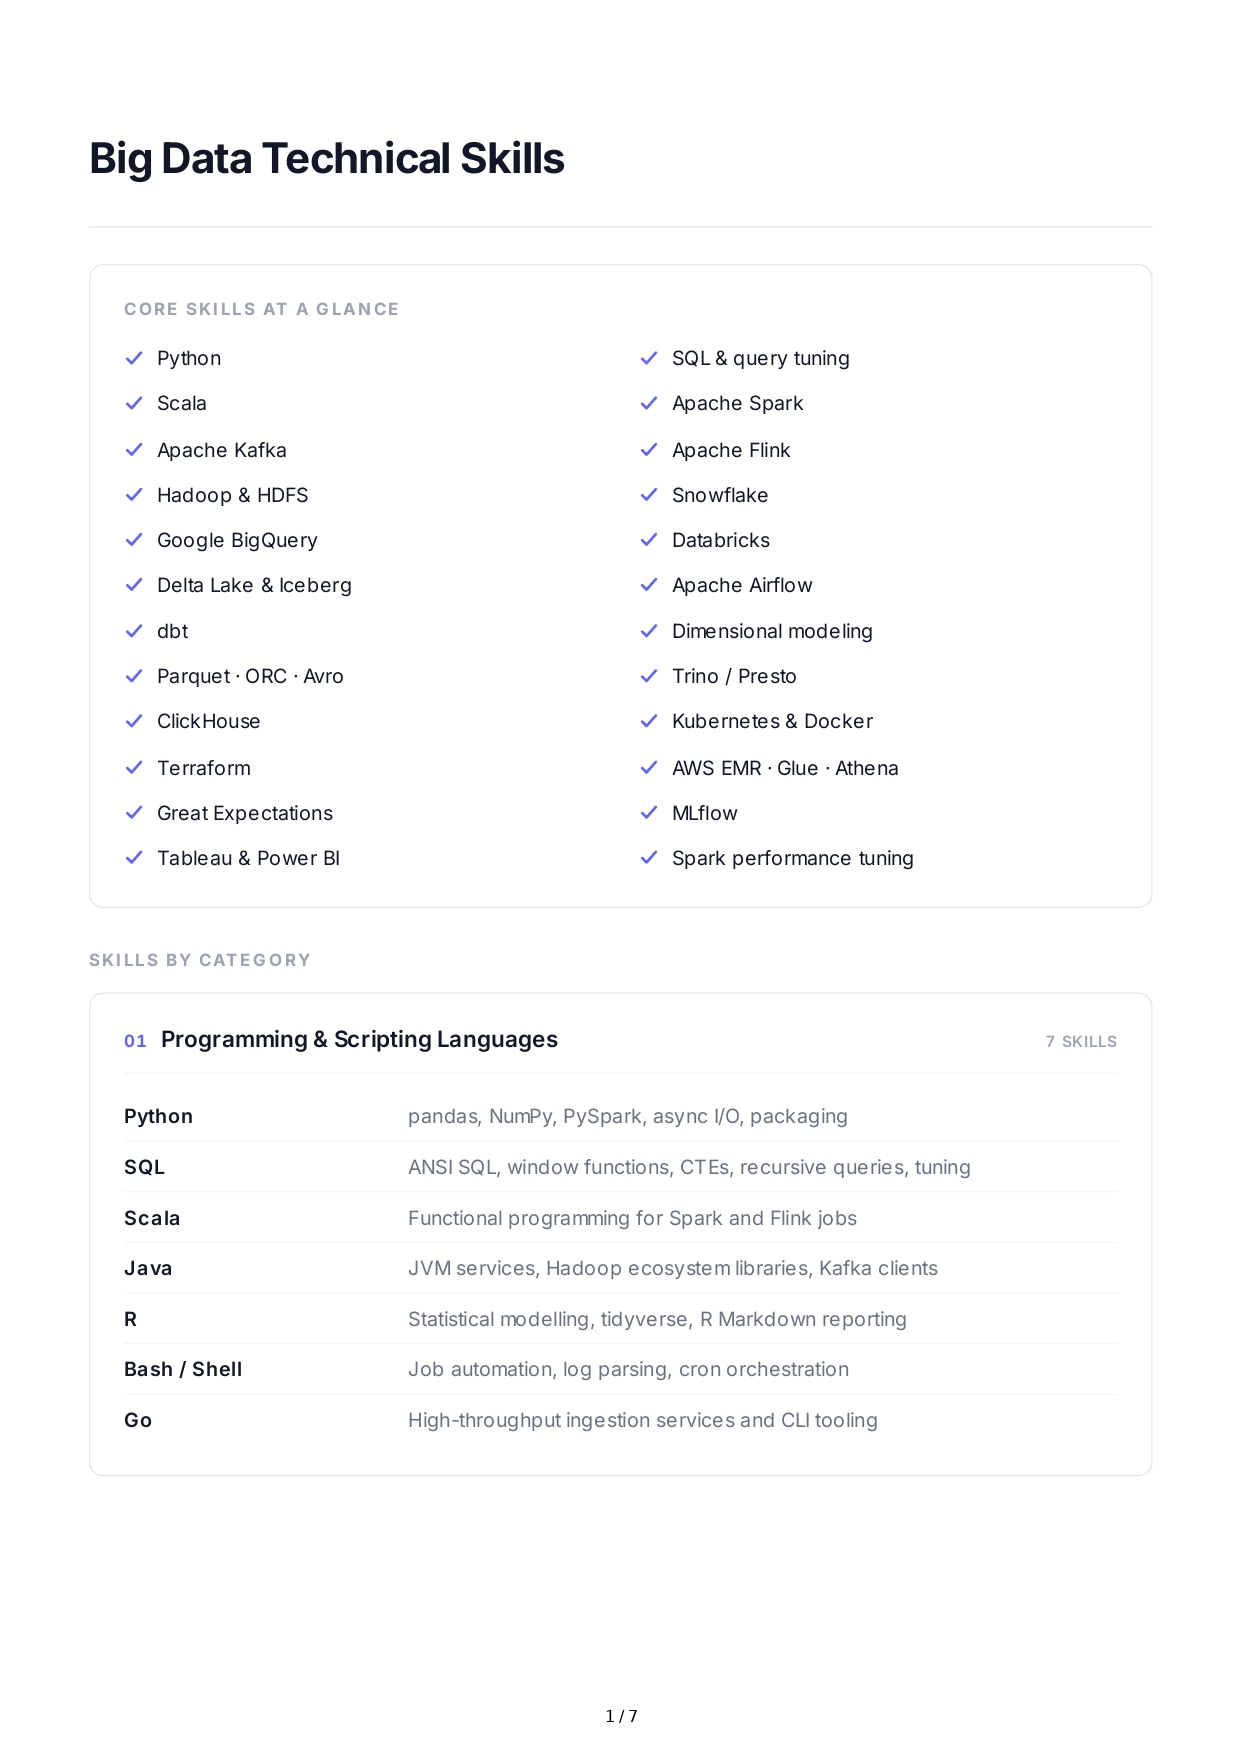
Python
pandas
NumPy
SciPy
statsmodels
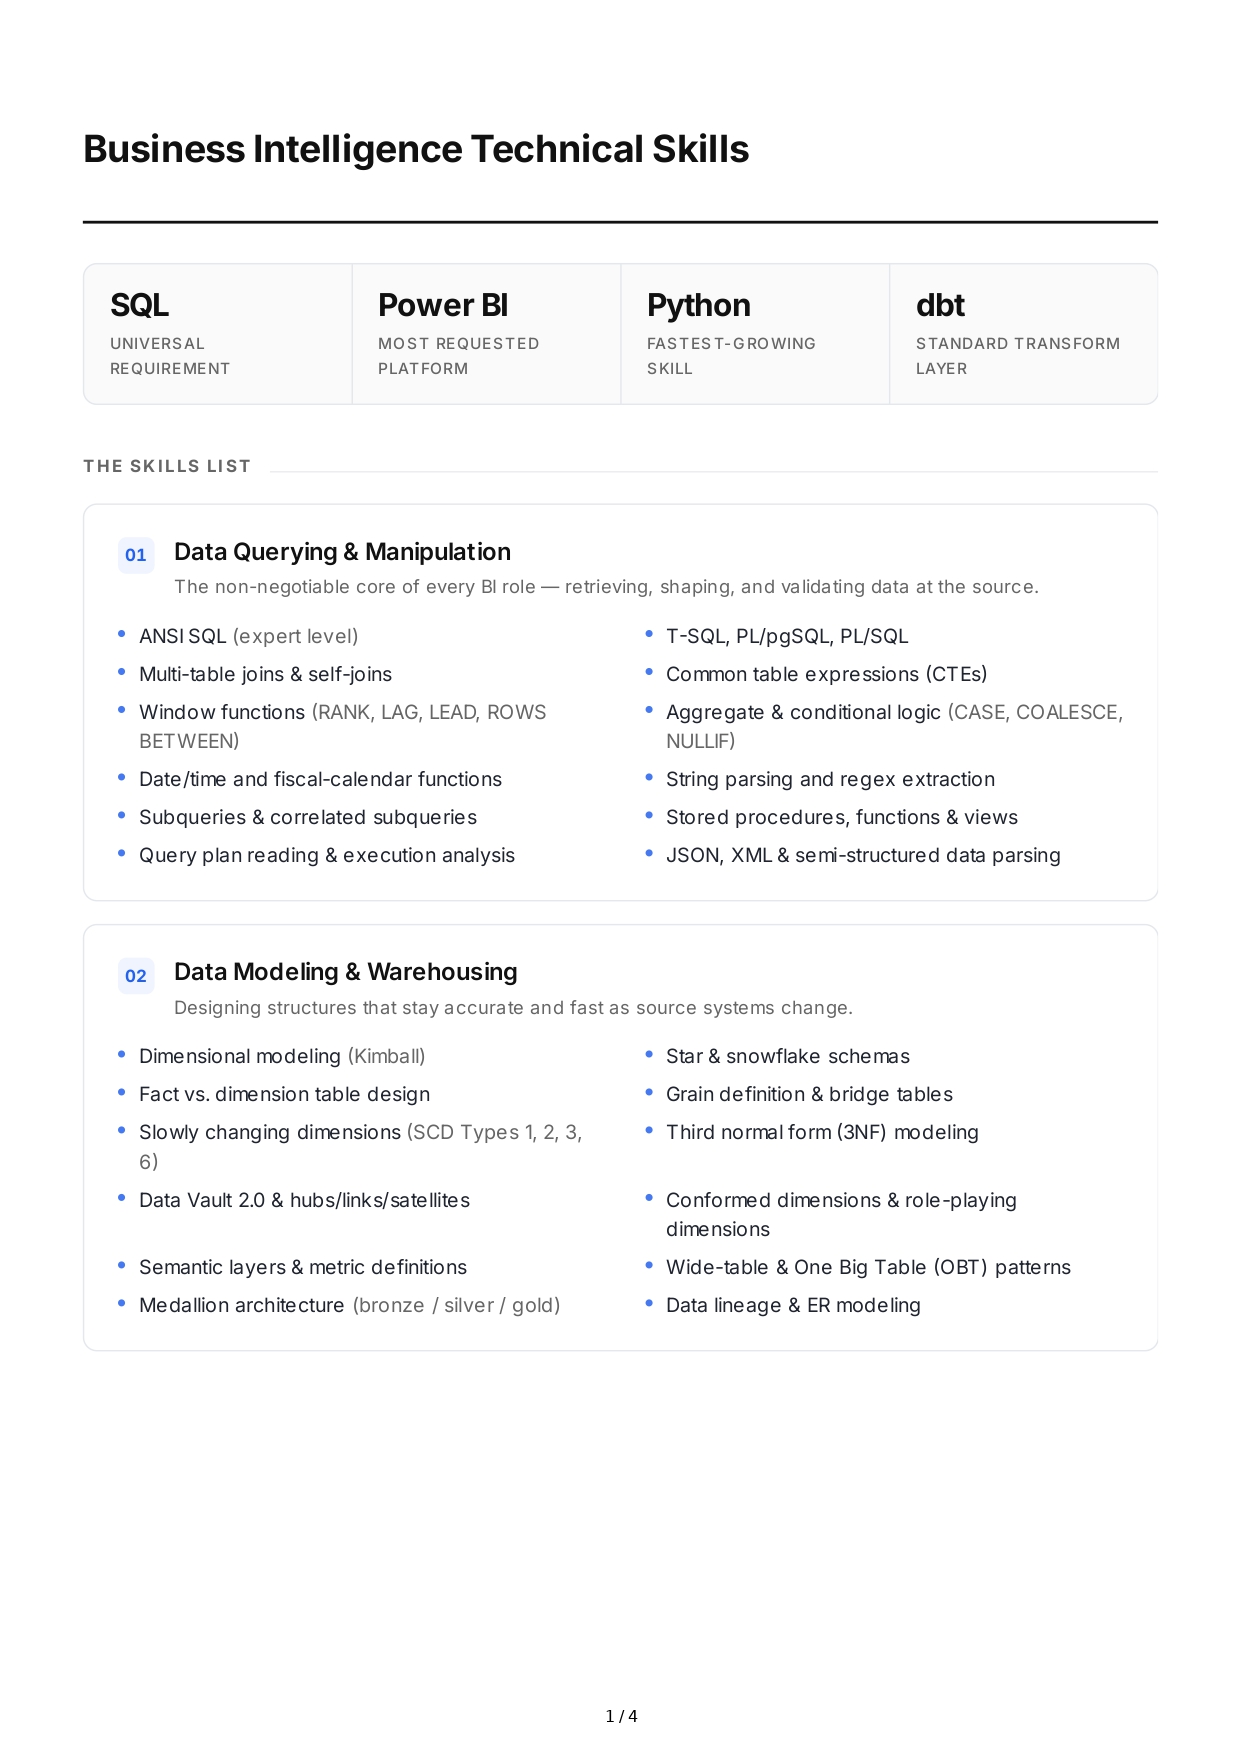
SQL
Window
functions
CTEs
Query
optimization
R
dplyr
&
tidyr
PySpark
Bash
/
shell
scripting
Git
&
GitHub
02
Statistics
&
Experimentation
Inference
,
uncertainty
,
and
the
design
of
trustworthy
tests
.
Descriptive
statistics
Sampling
&
survey
design
Hypothesis
testing
t
-
test
,
chi
-
square
,
ANOVA
Non
-
parametric
tests
OLS
regression
Logistic
regression
Ridge
&
lasso
Mixed
-
effects
models
A
/
B
testing
Power
analysis
&
sample
sizing
Sequential
testing
Causal
inference
Difference
-
in
-
differences
Propensity
score
matching
Bayesian
inference
Time
-
series
analysis
ARIMA
&
Prophet
Survival
analysis
03
Data
Wrangling
&
Preparation
Turning
raw
,
messy
source
data
into
analysis
-
ready
tables
.
Missing
-
value
treatment
Outlier
detection
Deduplication
Entity
resolution
Joins
&
merges
Pivoting
&
reshaping
Feature
engineering
Categorical
encoding
Scaling
&
normalization
Regex
&
text
parsing
Date
&
time
-
zone
handling
Data
profiling
Data
validation
(
Great
Expectations
)
04
Visualization
&
Business
Intelligence
Charting
,
dashboarding
,
and
communicating
findings
to
decision
-
makers
.
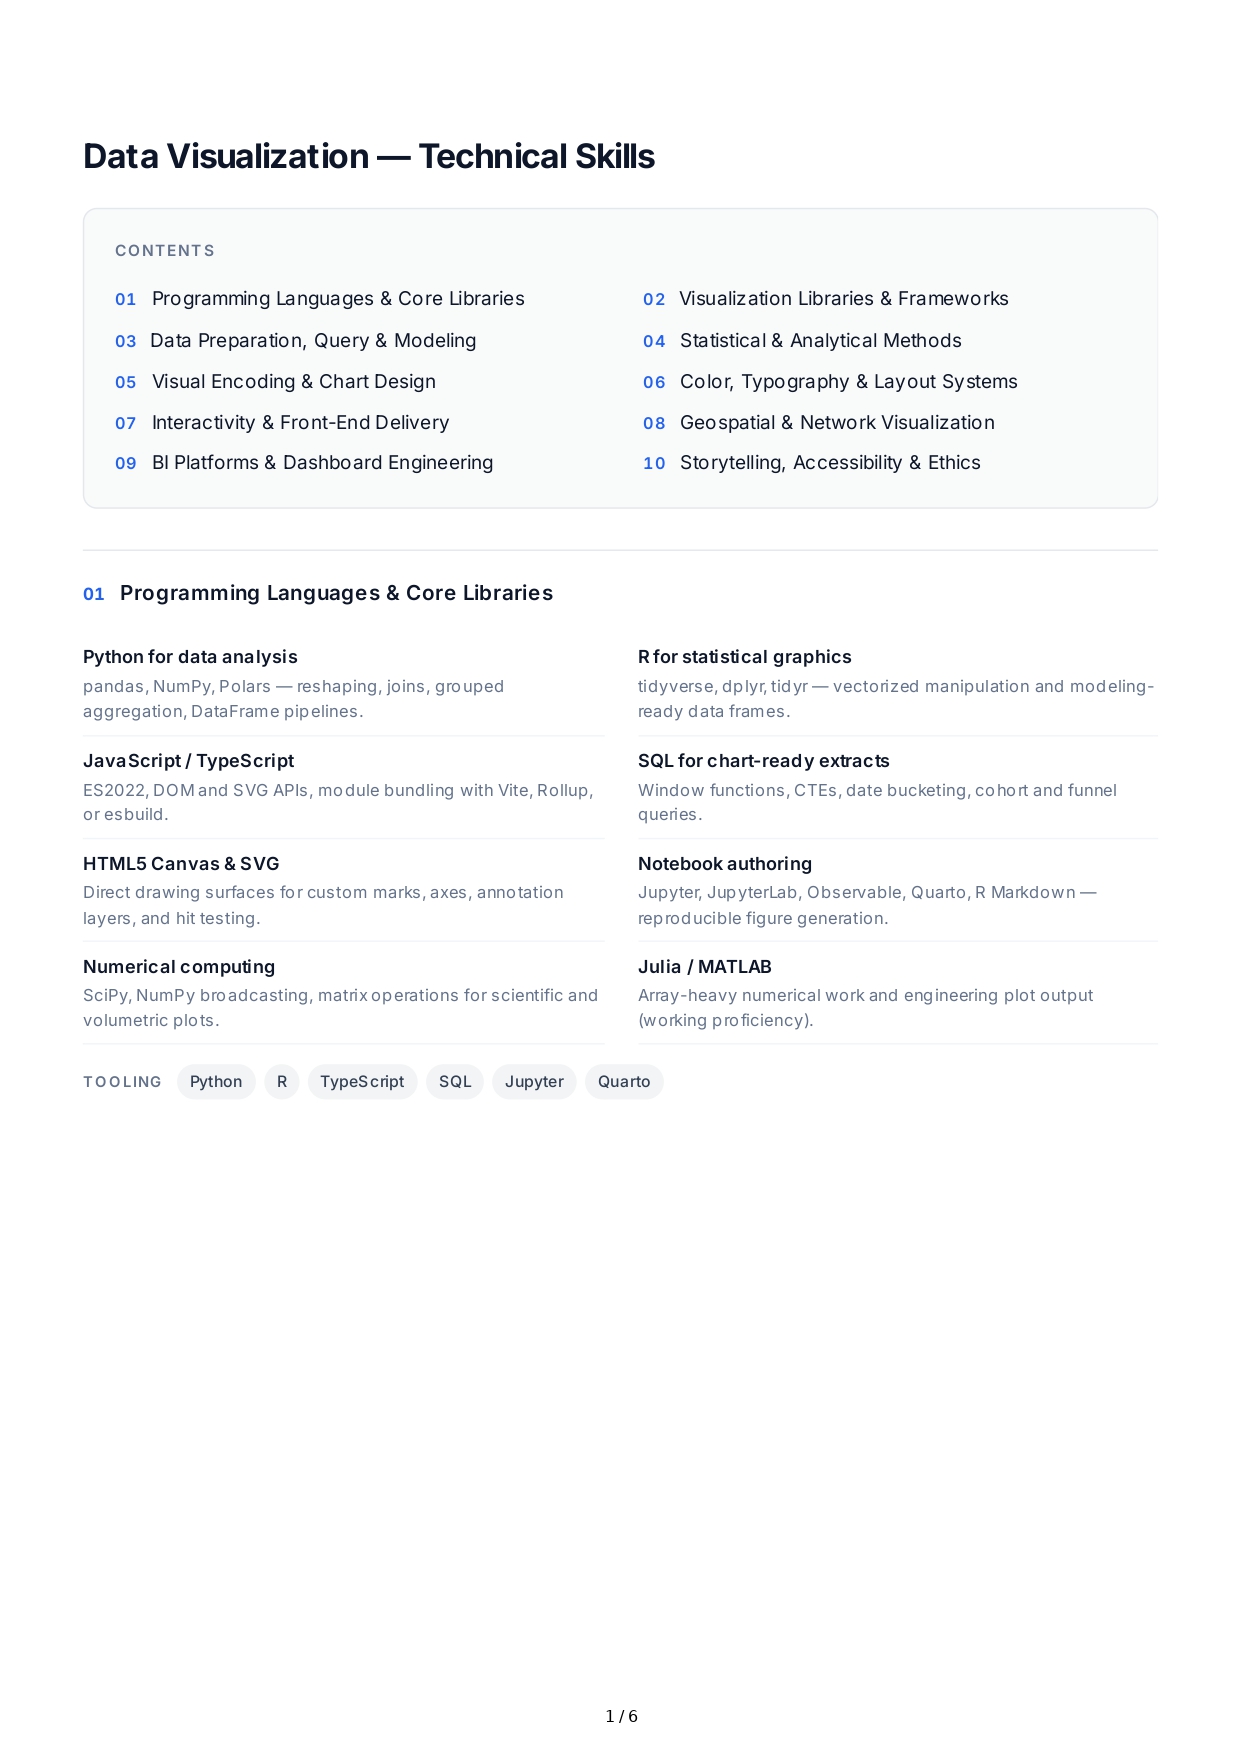
Tableau
LOD
expressions
Calculated
fields
Power
BI
DAX
Power
Query
Looker
/
LookML
Looker
Studio
Matplotlib
Seaborn
Plotly
Altair
ggplot
2
Chart
selection
Color
accessibility
Executive
reporting
1 / 3
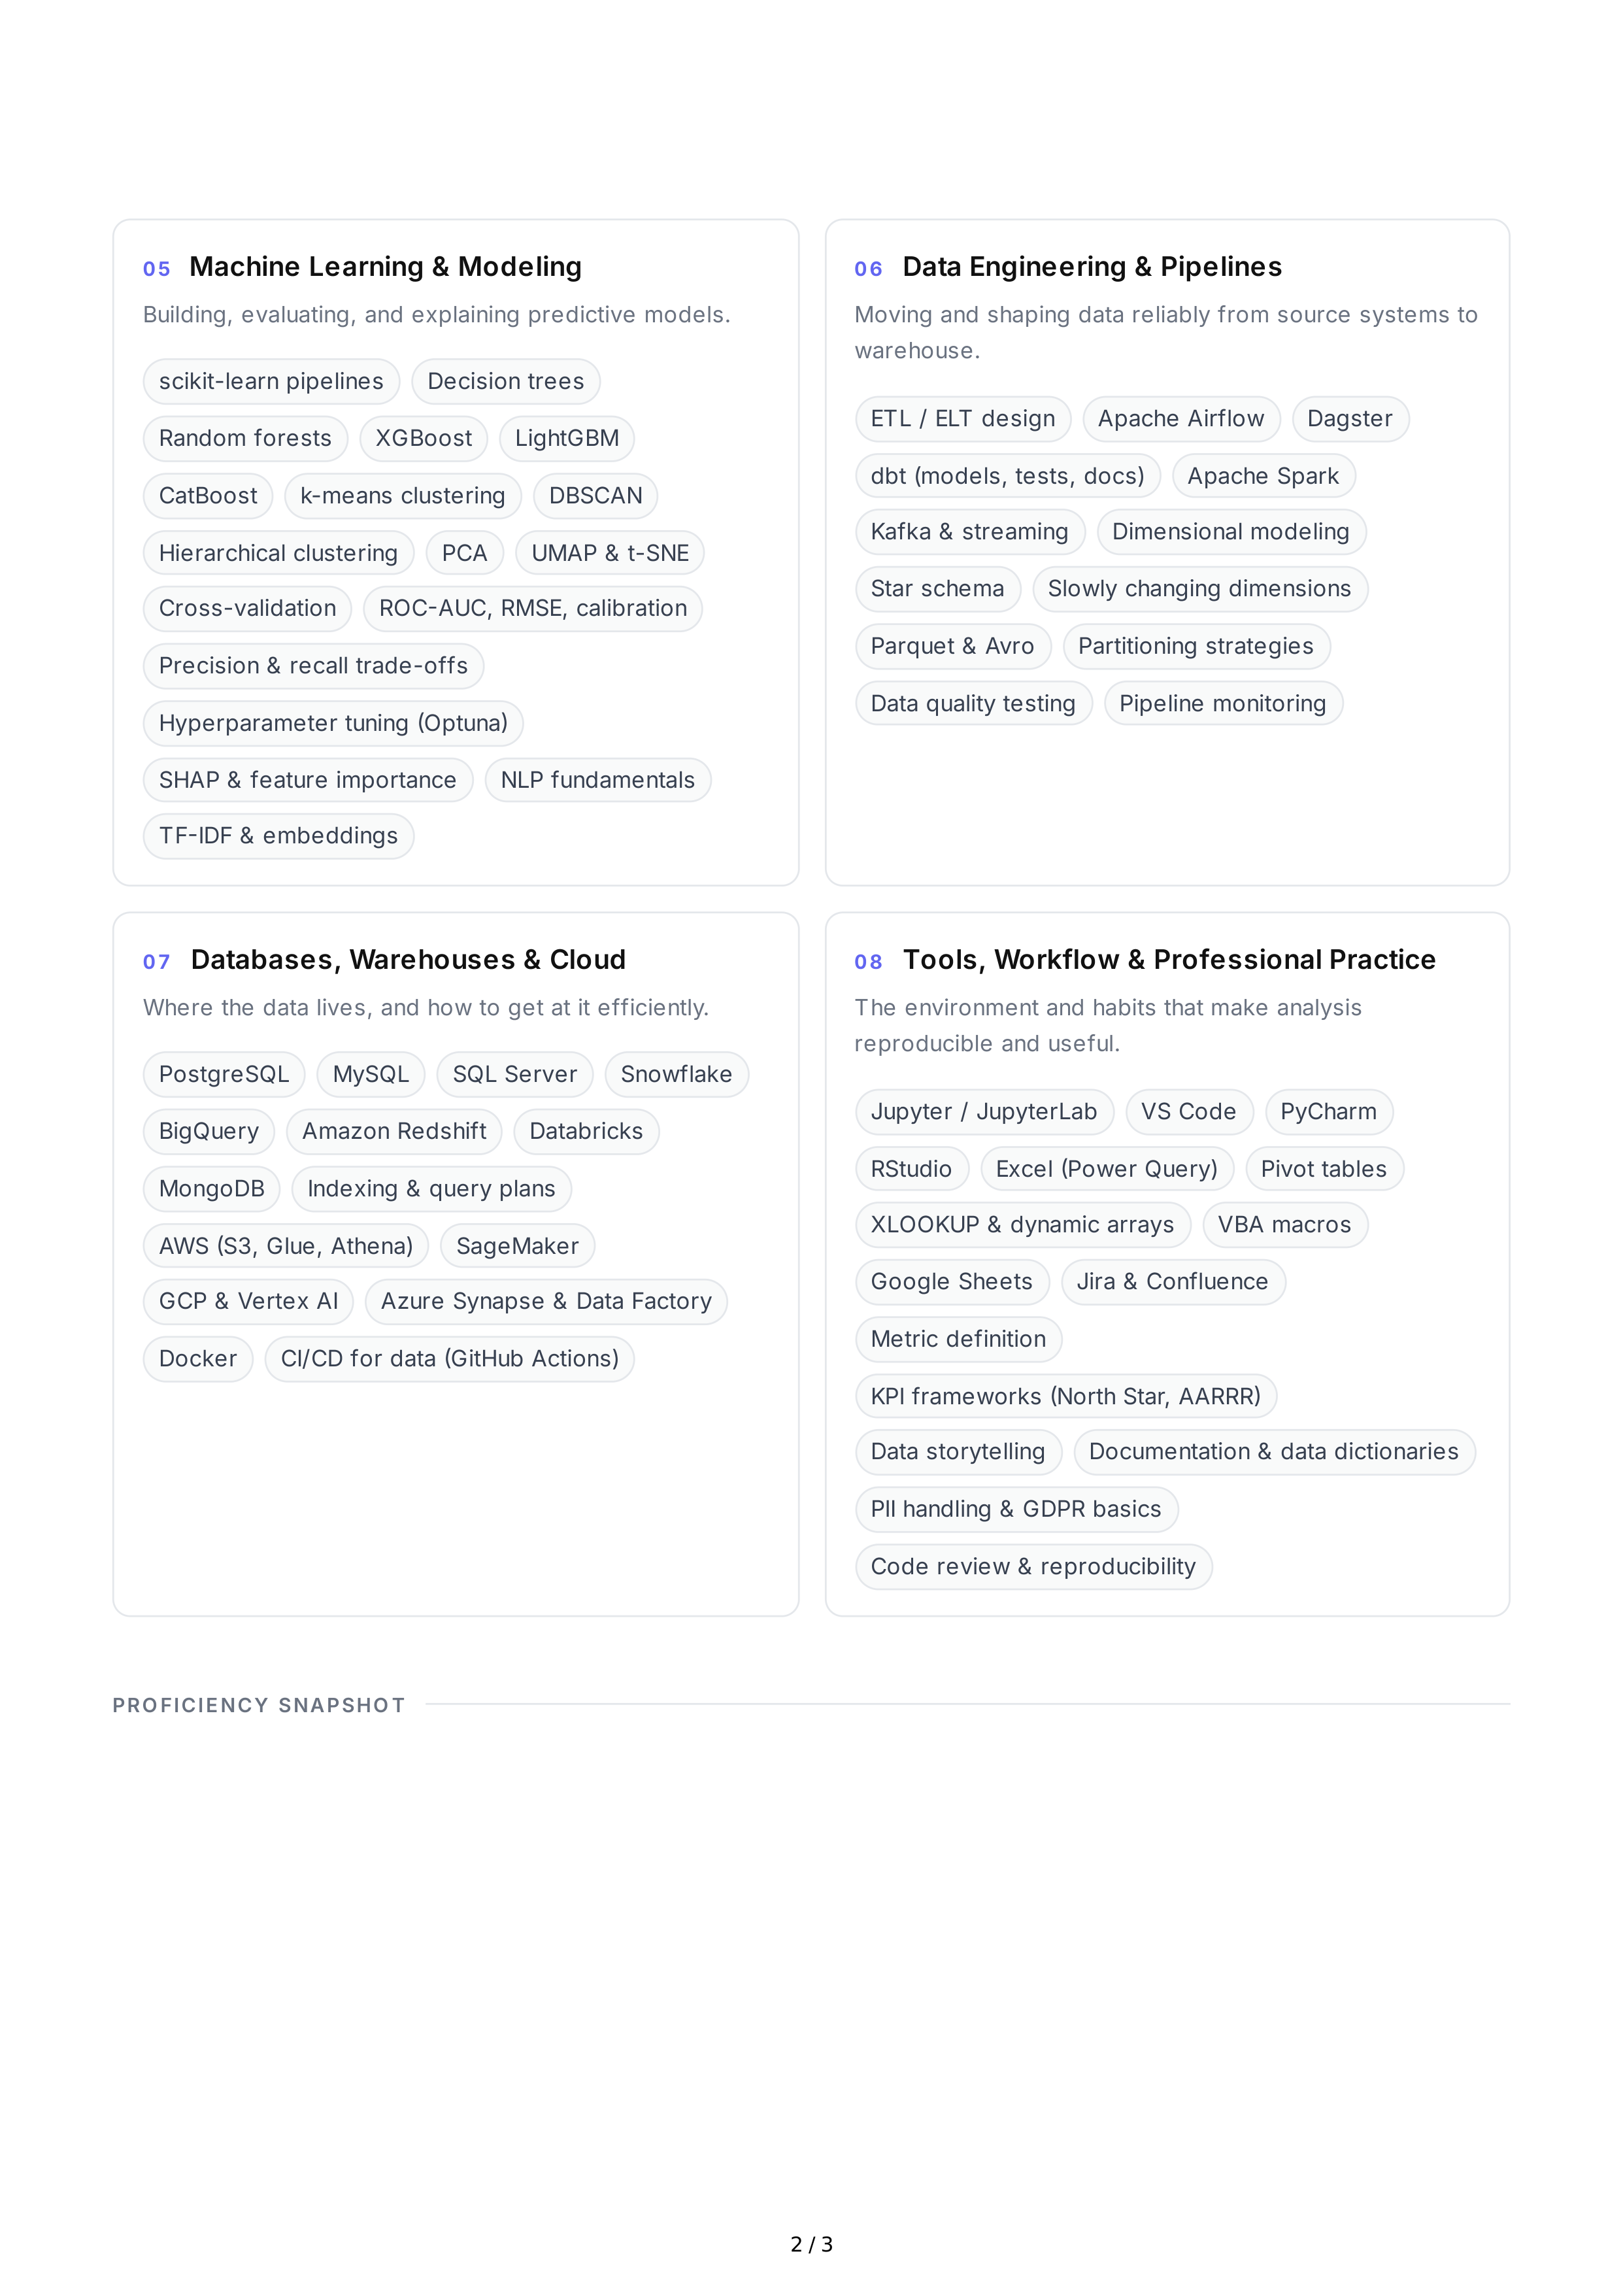
05
Machine
Learning
&
Modeling
Building
,
evaluating
,
and
explaining
predictive
models
.
scikit
-
learn
pipelines
Decision
trees
Random
forests
XGBoost
LightGBM
CatBoost
k
-
means
clustering
DBSCAN
Hierarchical
clustering
PCA
UMAP
&
t
-
SNE
Cross
-
validation
ROC
-
AUC
,
RMSE
,
calibration
Precision
&
recall
trade
-
offs
Hyperparameter
tuning
(
Optuna
)
SHAP
&
feature
importance
NLP
fundamentals
TF
-
IDF
&
embeddings
06
Data
Engineering
&
Pipelines
Moving
and
shaping
data
reliably
from
source
systems
to
warehouse
.
ETL
/
ELT
design
Apache
Airflow
Dagster
dbt
(
models
,
tests
,
docs
)
Apache
Spark
Kafka
&
streaming
Dimensional
modeling
Star
schema
Slowly
changing
dimensions
Parquet
&
Avro
Partitioning
strategies
Data
quality
testing
Pipeline
monitoring
07
Databases
,
Warehouses
&
Cloud
Where
the
data
lives
,
and
how
to
get
at
it
efficiently
.
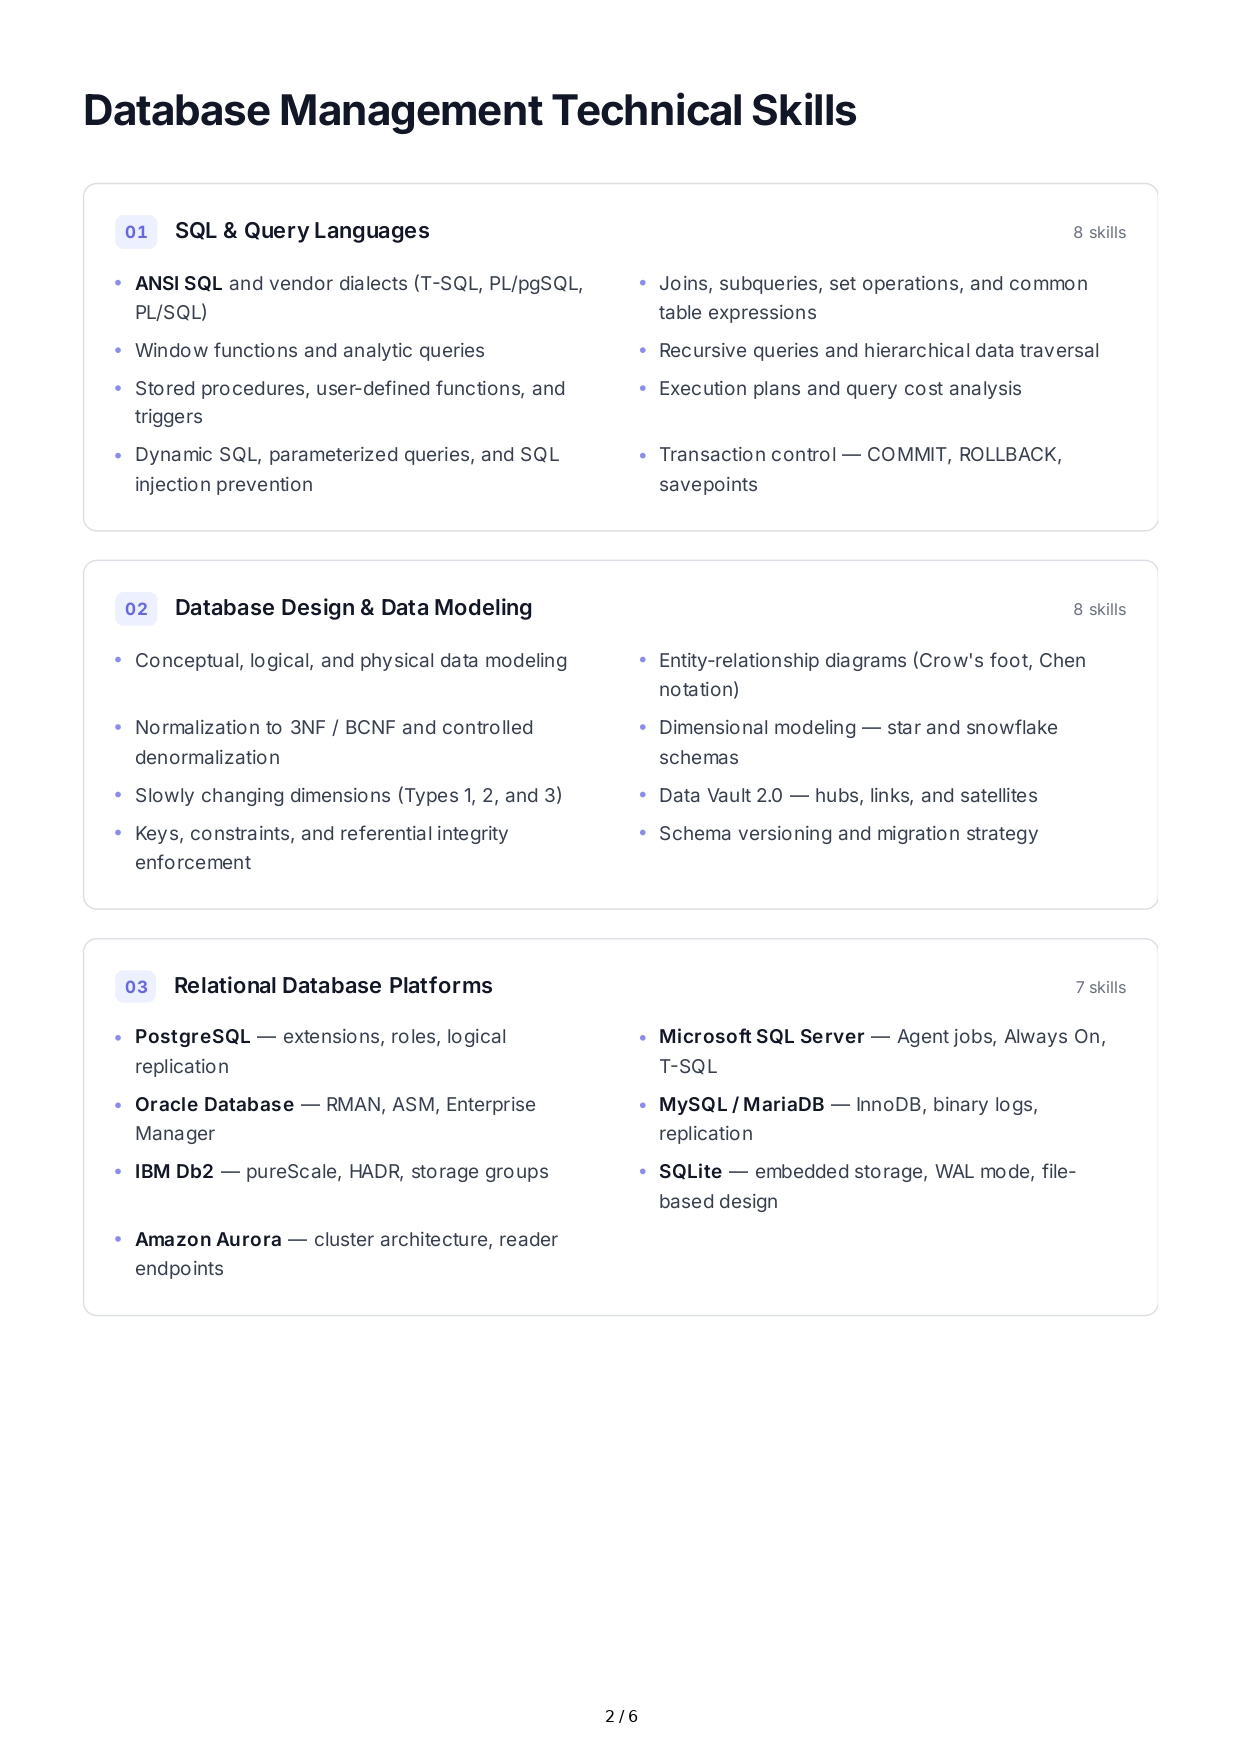
PostgreSQL
MySQL
SQL
Server
Snowflake
BigQuery
Amazon
Redshift
Databricks
MongoDB
Indexing
&
query
plans
AWS
(
S
3,
Glue
,
Athena
)
SageMaker
GCP
&
Vertex
AI
Azure
Synapse
&
Data
Factory
Docker
CI
/
CD
for
data
(
GitHub
Actions
)
08
Tools
,
Workflow
&
Professional
Practice
The
environment
and
habits
that
make
analysis
reproducible
and
useful
.
Jupyter
/
JupyterLab
VS
Code
PyCharm
RStudio
Excel
(
Power
Query
)
Pivot
tables
XLOOKUP
&
dynamic
arrays
VBA
macros
Google
Sheets
Jira
&
Confluence
Metric
definition
KPI
frameworks
(
North
Star
,
AARRR
)
Data
storytelling
Documentation
&
data
dictionaries
PII
handling
&
GDPR
basics
Code
review
&
reproducibility
PRO FICIE NCY
SNAPSHO T
2 / 3
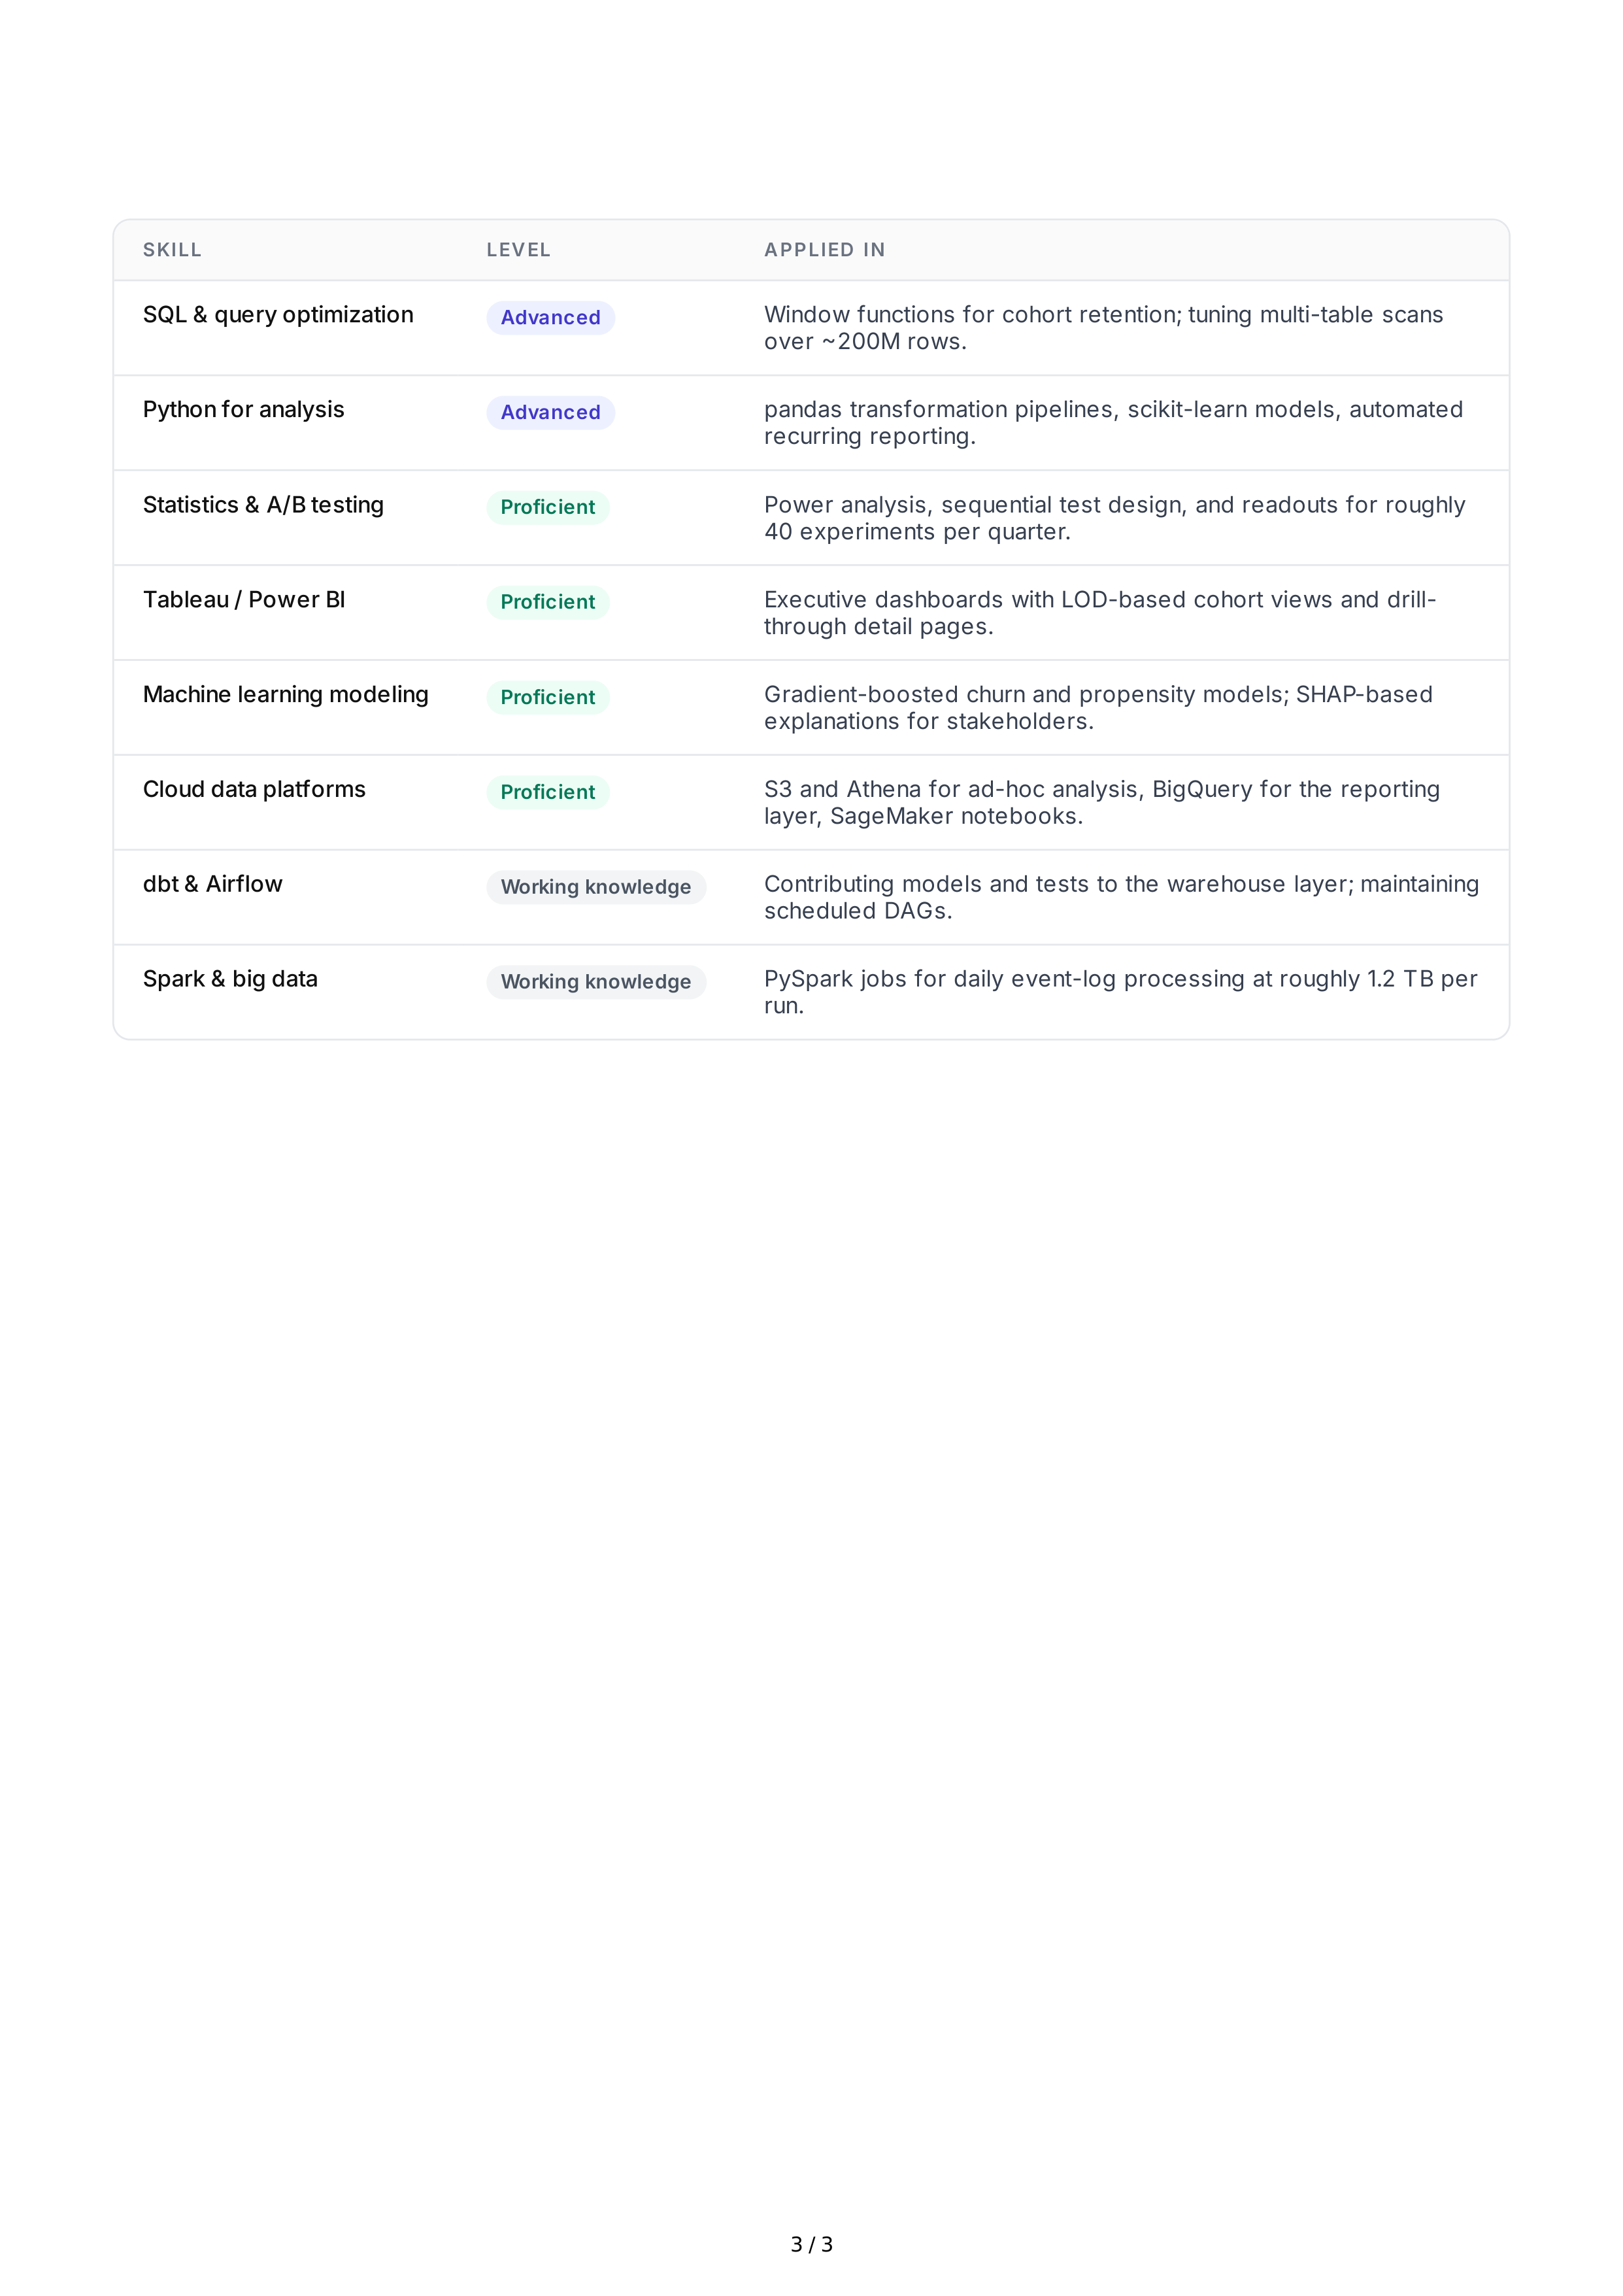
SKILL
LEVEL
APPLIED
IN
SQL
&
query
optimization
Advanced
Window
functions
for
cohort
retention
;
tuning
multi
-
table
scans
over
~200
M
rows
.
Python
for
analysis
Advanced
pandas
transformation
pipelines
,
scikit
-
learn
models
,
automated
recurring
reporting
.
Statistics
&
A
/
B
testing
Proficient
Power
analysis
,
sequential
test
design
,
and
readouts
for
roughly
40
experiments
per
quarter
.
Tableau
/
Power
BI
Proficient
Executive
dashboards
with
LOD
-
based
cohort
views
and
drill
-
through
detail
pages
.
Machine
learning
modeling
Proficient
Gradient
-
boosted
churn
and
propensity
models
;
SHAP
-
based
explanations
for
stakeholders
.
Cloud
data
platforms
Proficient
S
3
and
Athena
for
ad
-
hoc
analysis
,
BigQuery
for
the
reporting
layer
,
SageMaker
notebooks
.
dbt
&
Airflow
Working
knowledge
Contributing
models
and
tests
to
the
warehouse
layer
;
maintaining
scheduled
DAGs
.
Spark
&
big
data
Working
knowledge
PySpark
jobs
for
daily
event
-
log
processing
at
roughly
1.2
TB
per
run
.
3 / 3