Netflix Monolith to Microservices AWS Migration Action Plan
Page 5
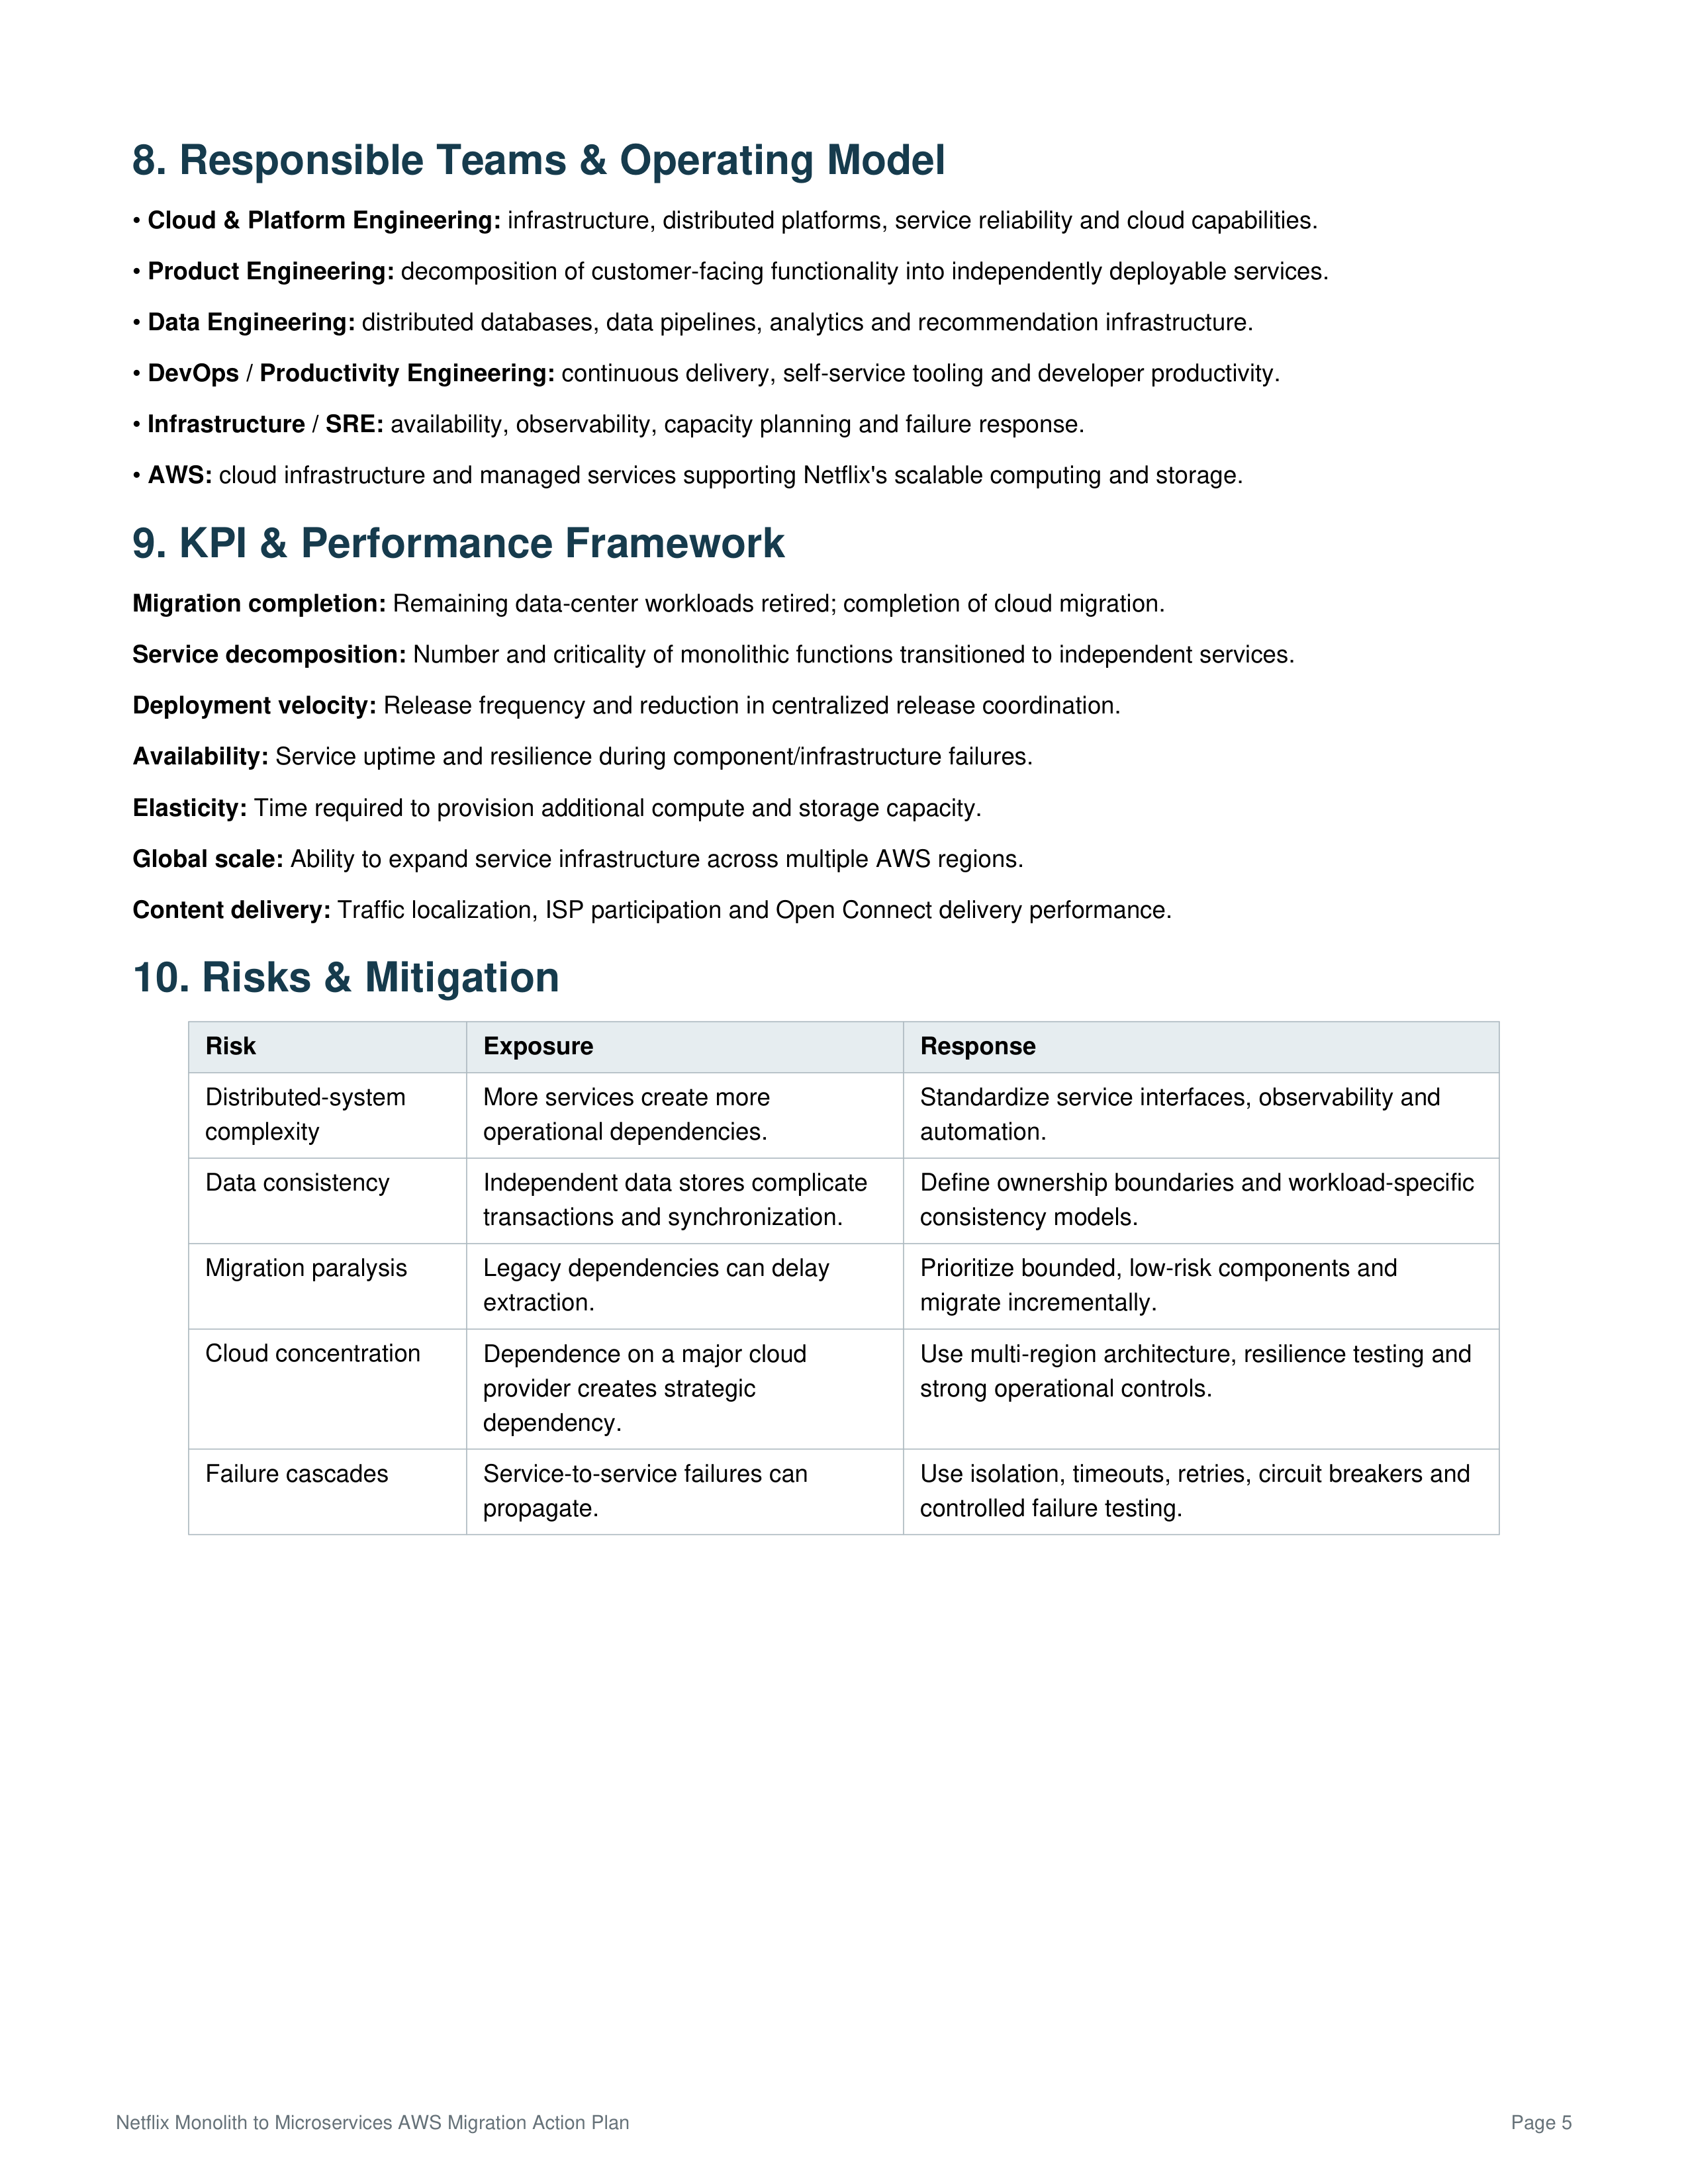
8. Responsible Teams & Operating Model
•
Cloud & Platform Engineering:
infrastructure, distributed platforms, service reliability and cloud capabilities.
•
Product Engineering:
decomposition of customer-facing functionality into independently deployable services.
•
Data Engineering:
distributed databases, data pipelines, analytics and recommendation infrastructure.
•
DevOps / Productivity Engineering:
continuous delivery, self-service tooling and developer productivity.
•
Infrastructure / SRE:
availability, observability, capacity planning and failure response.
•
AWS:
cloud infrastructure and managed services supporting Netflix's scalable computing and storage.
9. KPI & Performance Framework
Migration completion:
Remaining data-center workloads retired; completion of cloud migration.
Service decomposition:
Number and criticality of monolithic functions transitioned to independent services.
Deployment velocity:
Release frequency and reduction in centralized release coordination.
Availability:
Service uptime and resilience during component/infrastructure failures.
Elasticity:
Time required to provision additional compute and storage capacity.
Global scale:
Ability to expand service infrastructure across multiple AWS regions.
Content delivery:
Traffic localization, ISP participation and Open Connect delivery performance.
10. Risks & Mitigation
Risk
Exposure
Response
Distributed-system
complexity
More services create more
operational dependencies.
Standardize service interfaces, observability and
automation.
Data consistency
Independent data stores complicate
transactions and synchronization.
Define ownership boundaries and workload-specific
consistency models.
Migration paralysis
Legacy dependencies can delay
extraction.
Prioritize bounded, low-risk components and
migrate incrementally.
Cloud concentration
Dependence on a major cloud
provider creates strategic
dependency.
Use multi-region architecture, resilience testing and
strong operational controls.
Failure cascades
Service-to-service failures can
propagate.
Use isolation, timeouts, retries, circuit breakers and
controlled failure testing.